The exception was supposed to last a quarter. Two years later it is still running, three other systems depend on it, and the one engineer who understood why it was granted has left the company.
It usually starts like this. A team has to connect a new logistics partner before a launch date. The standard says partner data comes in through the integration platform, which checks it, records every delivery, and alerts someone when one fails. The platform cannot read this partner’s file format yet, and adding it will take three months the launch does not have. So the team asks for an exception: a small script on a single server that picks up the partner’s file every night and writes it straight into the orders database, using a password exempt from the usual rotation rule because changing it would break the script. Everyone agrees this is reasonable. Everyone agrees it is temporary.
Then the launch succeeds and the pressure moves elsewhere. Six months later the platform team adds the new file format, but nobody migrates the script, because it works and the people who asked for it are busy. The finance team starts reconciling invoices against the table the script fills. A second partner is connected “the same way as the first one,” because that path now exists. The server’s operating system approaches the end of its support. The engineer who wrote the script changes jobs. Nobody ever decided to make the script part of the architecture. It simply never stopped being there.
The story is hypothetical, but anyone who has run production systems has a version of it. It shows something organizations rarely say out loud: the architecture you actually operate is not only what you chose to design. It is that design plus every exception you approved and never revisited.
What an exception actually is
A standard is a decision made once so it does not have to be made every time. “All partner data goes through the integration platform” settles in advance how data is checked, who hears about a failure, and how a bad delivery is recovered. The deployment pipeline, the monitoring rules, the approved technologies: each is a question answered once, so every team can rely on the answer without reopening it.
An exception is permission to skip one of those answers, in one case, for a reason. It might mean bypassing the pipeline for an urgent fix, running a database the platform team does not support, or opening a network path the security model normally forbids. The request almost always arrives as a local, short-lived matter, and that is how it gets approved.
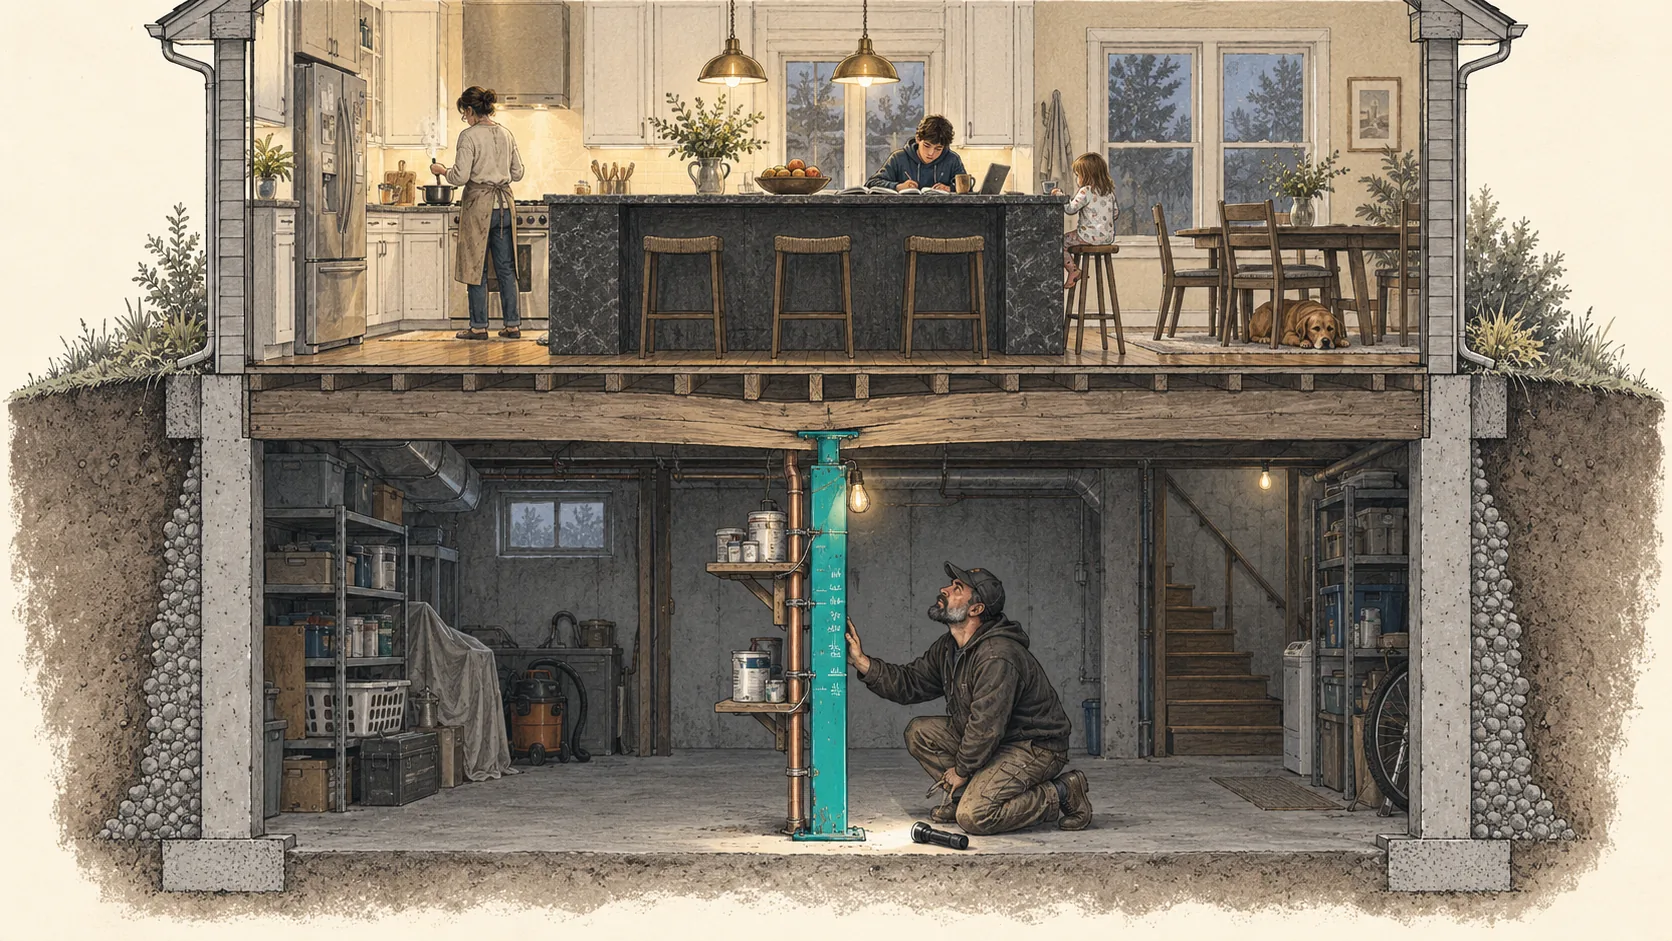
Think about an old house with a beam in the basement that has started to sag. Someone puts a steel post under it “for now,” meaning to replace the beam properly once there is money. Years pass. The kitchen upstairs is remodeled, and a heavy granite island ends up right above that post. When a new owner finally wants to open up the basement, the contractor’s first question is not why the post is there. It is what will happen when it comes out. Nobody designed the kitchen to rest on that post, but it does now. That is what load-bearing means: take it away and something above it moves.
Exceptions become load-bearing the same way: not by decision, but because other things get built on top of them while nobody is watching.
Approval is a moment; the obligation is not
Approving an exception feels like an event. Someone reviews the request, weighs the immediate risk, and says yes, and the ticket closes. But four things start at that moment, and none of them closes with the ticket.
The first is a path that has to keep working. The script now needs a server, security patches, a credential, and someone who notices when it fails, and the standard tooling that would have provided all of that does not reach it. The second is a dependency. Anything that can be observed will eventually be relied on: once the script fills a table, someone reads that table, and the exception acquires users its approver never heard of. Software engineers have a name for the general pattern, Hyrum’s Law: with enough users, every observable behavior of a system will be depended on by somebody, whatever its documentation promises. The third is a precedent, which the next team with a deadline will cite. The fourth is knowledge that lives in one or two heads, because the documentation describes the standard path and the exception is, by definition, not on it.
The request rarely makes any of this visible. It asks for one thing, for a short time. The commitments appear later, and they do not expire when the original justification does. The platform learned to read the partner’s format, and the reason for the exception disappeared. The exception did not.
This is why exceptions describe a system so accurately. A diagram shows the intended architecture; the list of approved exceptions shows the one that is running: the manual deployment, the unmonitored service, the direct database connection. Past a certain point, that list is the better architecture document.
The bill arrives later, and someone else pays it
Exceptions look cheap at approval because the benefit is immediate and the cost is deferred and spread out, over years, in pieces small enough that nobody adds them up.
Every exception needs its own testing, because it no longer follows the path the standard tests cover. Monitoring has to be extended to it, or it becomes a blind spot: the nightly script that fails silently is discovered when finance finds a week of missing invoices. Support questions concentrate in the few people who understand the deviation, so local knowledge turns into a single point of failure. Recovery gets harder, because the procedure describes the standard path, not the special one. And every security review flags the password that never changes, until someone renews the waiver again.
There is also an asymmetry between who decides and who pays. The person who approves an exception usually collects the visible reward: the launch shipped, the blocker cleared. The people who carry it are the operators, the engineers on call at night, the next team to touch the system, and the auditors, often years later and elsewhere in the organization. The bill rarely carries the approver’s name. An approval process that never asks about future cost is not neutral. It is built to lean toward yes.
The most expensive cost is precedent, and it is the easiest to miss. “They were allowed to do it, so why can’t we?” is hard to answer once the first approval exists. The second partner comes in through the nightly script because the path is already there and refusing would look arbitrary. The standard erodes through a series of comparisons, each of which sounds fair on its own. Nobody formally abandons it. The organization grants the same deviation often enough that the deviation becomes normal, and the standard becomes the thing people have to argue for.
Why nobody takes it out
If exceptions cost this much, why do they survive? Because keeping one costs nothing visible this quarter, and removing one costs a project.
To remove the script, someone has to find everything that depends on it, and those dependents were never recorded, because the exception was never supposed to have any. Someone has to move the data onto the standard path, test it against finance’s reconciliation, and schedule the switch. That work competes with new features, and its success is invisible by design: if it goes well, nothing changes for anyone. Its failure would be very visible. For whoever makes the call this week, leaving the script alone always looks safer.
Time makes it worse. As the people who granted the exception move on, the reason for it fades, and a component nobody can explain is frightening to touch. The longer an exception runs, the more it is protected by the same ignorance that made it risky. “Temporary” ends up describing the intention, not the lifespan.
Not every deviation is a mistake
It would be wrong, and impractical, to treat every deviation as a failure. Serious architecture has to handle conditions the standard did not anticipate. A regulation specific to one market, a performance constraint someone actually measured, or a system inherited through an acquisition can each justify a different path. Refusing every exception does not produce a pure architecture. It produces teams that route around it without asking, and the same deviations with no record at all.
The problem is not that deviations exist. It is that most of them never get a status. They are granted as one thing and then drift, unexamined, into something else. A deviation can honestly be in one of three states, and there is a fourth it reaches by default.
Practical Framework
The four states of a deviation
Every departure from a standard is in one of these states, whether or not anyone has said which:
- Temporary exception. A bounded departure with a named owner, an expiry date, and stated conditions for returning to the standard. The organization knows what it stepped away from and when it is due back.
- Technical debt. A known compromise that makes future change or operation harder, acknowledged as such, with an explicit decision about whether and when to pay it down. Nobody expects it to go away on its own, and nobody pretends it will.
- Deliberate capability. A deviation that serves a lasting need and has been promoted into the standard: designed, funded, monitored, documented, and supported like everything else. At that point it is no longer an exception; the standard has grown to include it.
- Unacknowledged architecture. A deviation whose expiry date passed without a decision. It keeps running, keeps gathering dependents, and is still described everywhere as temporary. Nobody chose this state. It is where every exception ends up when nobody chooses for it.
The first three are legitimate. The fourth is the one this article is about, and the only way out of it is a decision.
The moment that matters is the review date. When an exception reaches it, there are four honest outcomes: remove it, renew it with fresh evidence that the reason still holds, reclassify it as debt with a funded plan, or promote it into a supported capability. Letting it continue without any of those is a fifth outcome, and it is not a neutral one. It moves the exception into the fourth state.
Apply that to the nightly script. Once the platform could read the partner’s format, the reason was gone, and the honest outcome was removal. Had the platform team decided never to support that format, the script should have been promoted: proper monitoring, a password that changes on schedule, a named owner, and a place on the architecture diagram. Either answer would have been defensible. What actually happened, nothing, was the only one that was not.
Hard to forget, not hard to get
If exceptions will become architecture either way, the only real choice is whether they do so deliberately. In practice, every approval should record a few things, in a place where the next person will actually look: who owns it, meaning the person or team who will run it and one day remove it, which is not always whoever asked for it; what it covers, what it deliberately leaves out, and why the standard does not fit; what it will cost to keep, in testing, monitoring, support, and recovery, so the decision is made with the price in view; when it will be reviewed; and what would let it return to the standard.
Three practices keep this from turning into forms nobody reads. First, record exceptions where architectural decisions already live. An exception is a decision with consequences, like any other the team records, and it belongs beside the standard it departs from, not in a closed ticket. Second, give the review date teeth. When it passes without a decision, the default should be escalation back to whoever approved it, not silent renewal; an expiry date nobody enforces is only a hopeful one. Third, treat the open exceptions as a budget, with a rough ceiling and a standing review. Once the ceiling is reached, a new exception should create pressure to retire an old one instead of joining a list that only grows.
None of this makes exceptions harder to get, and it should not. A team with a real deadline and a real reason should still get a fast yes. The goal is to make every exception impossible to forget, because an architecture is not only what an organization draws. It is also what it allows, again and again, until accommodation becomes structure.
So start with one. Find the oldest exception still running in your environment, the one everyone still calls temporary. Ask who owns it today, what it costs to keep, what depends on it, and when anyone last decided to keep it. If nobody can answer, it is not an exception anymore. It is part of your architecture, and someone should decide that on purpose.
Key takeaway. Every deviation needs an explicit state. A temporary exception needs an owner, an expiry date, and a review that actually happens; debt needs an acknowledged cost and a funded decision; a lasting need should become a supported capability. When none of those decisions is made, the exception becomes architecture by default.
Source notes
These sources support the treatment of architecture decisions, technical debt, and unplanned dependency. The partner integration and the basement post are hypothetical illustrations. The four-state model and the cost asymmetry between approvers and operators are this article’s synthesis and are not attributed to any source.
- Recording a decision with its consequences. Nygard proposes the architecture decision record as a short, durable account of a decision’s context, the decision itself, and its consequences. It supports recording exceptions beside the standards they depart from. Source: Michael Nygard, “Documenting Architecture Decisions”, 2011.
- Technical debt as a managed choice. The Software Engineering Institute treats technical debt as a managed set of design or implementation choices that affect future delivery, rather than as a synonym for every nonstandard decision. Source: Software Engineering Institute, “Managing Technical Debt”.
- Observable behavior attracts dependents. Hyrum Wright observes that, with enough users of an interface, every observable behavior of a system will be depended on by somebody, regardless of what its contract promises. Source: Hyrum’s Law.
Discuss this article
Thoughtful comments, corrections, and notes from real-world practice are welcome. Discussion is managed through GitHub.
This space is intended for meaningful technical discussion, useful corrections, and field experience. Spam, personal attacks, low-effort comments, and vendor pitches may be removed.